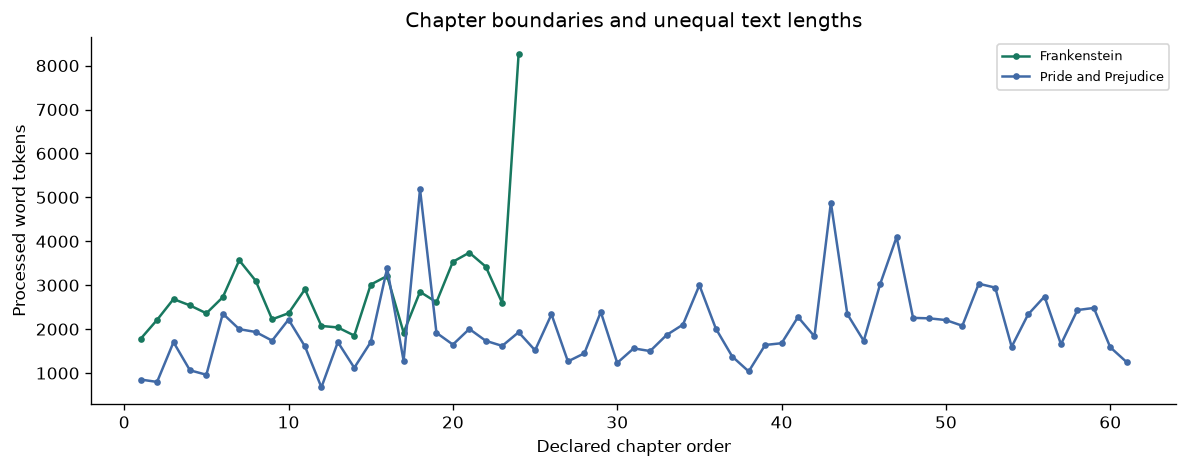
Audit a historical text corpus
Preserve source ebooks and licenses, inspect chapter boundaries and make tokenization decisions visible.
numpy · pandas · matplotlib · IPython
6 independent, runnable lessons connecting questions, traceable inputs, transparent methods and interpretation. One notebook download starts each workflow.
6 recipes
Preserve source ebooks and licenses, inspect chapter boundaries and make tokenization decisions visible.
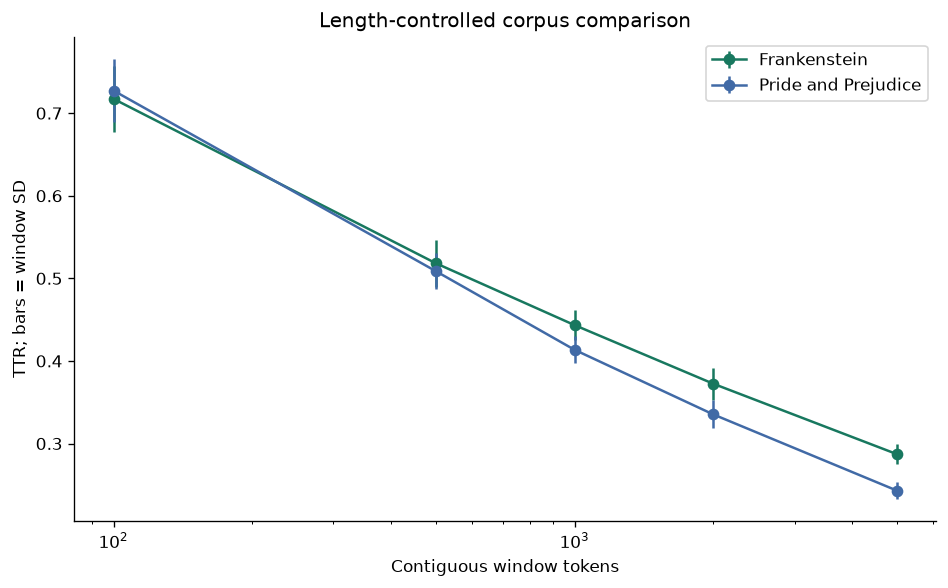
Separate whole-corpus token/type counts from matched-window vocabulary ratios and inspect length effects.
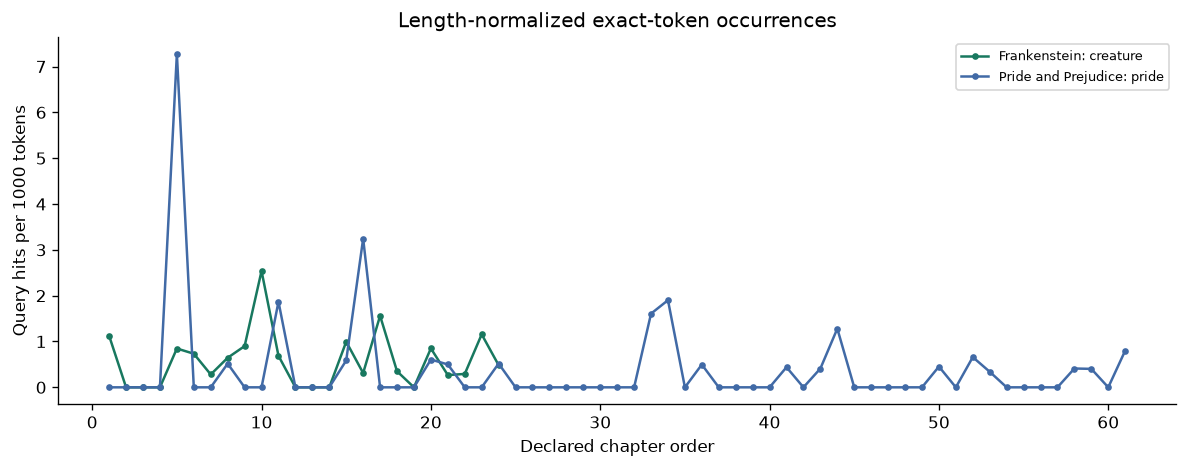
Retrieve every exact-token match with context, inspect chapter-normalized counts and return to the source passages.
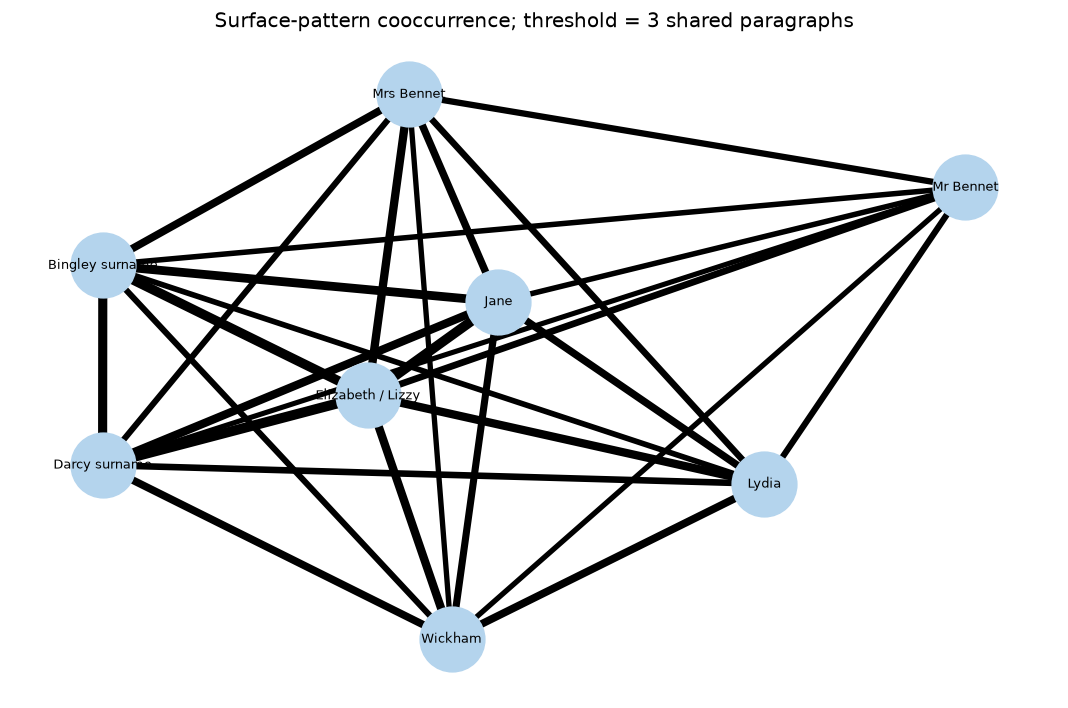
Declare surface-pattern aliases, count paragraph cooccurrences and inspect threshold-sensitive graph summaries.
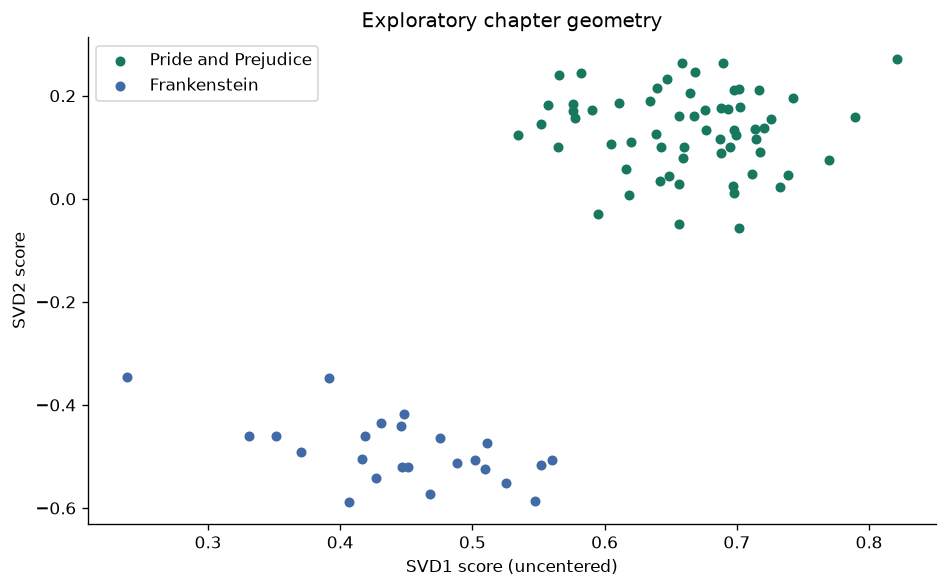
Build a declared chapter vocabulary, compute normalized TF-IDF and interpret an uncentered SVD without treating axes as topic probabilities.
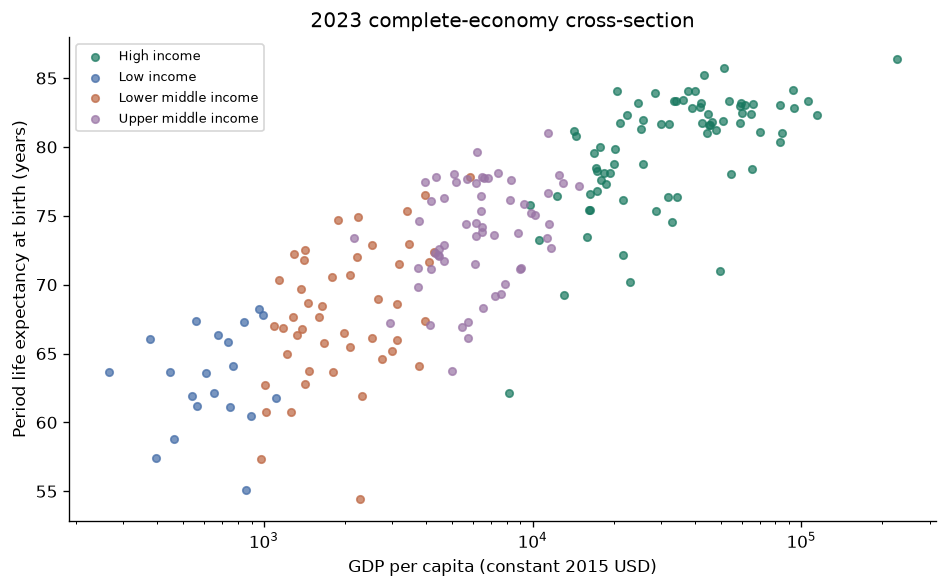
Join economy-level income, population and life-expectancy observations, audit missingness and distinguish association from individual or causal inference.
No matching recipes. Try another query or topic.